
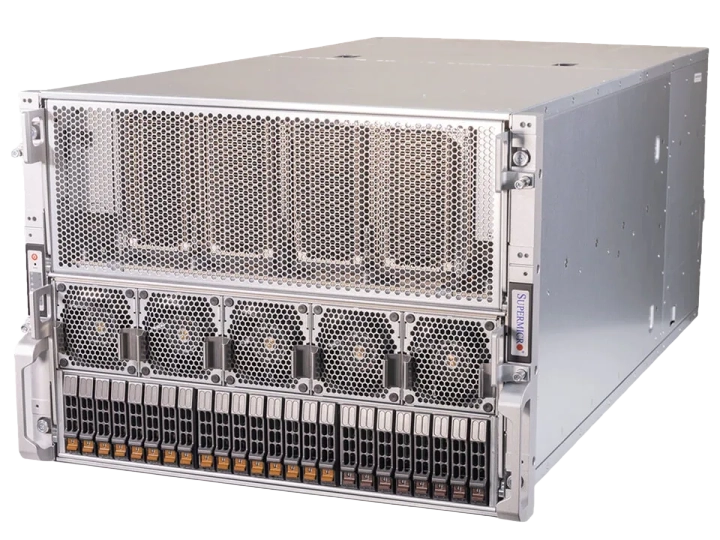
Qubrid LLM Gen AI Appliance Server 8 x NVIDIA H200 141GB HGX NVLink GPU
Power your next-gen generative AI, LLM training and inference workloads with 8 × NVIDIA HGX™ H200 141GB NVLink. Built for performance, scalability and enterprise reliability.
8 × GPUs
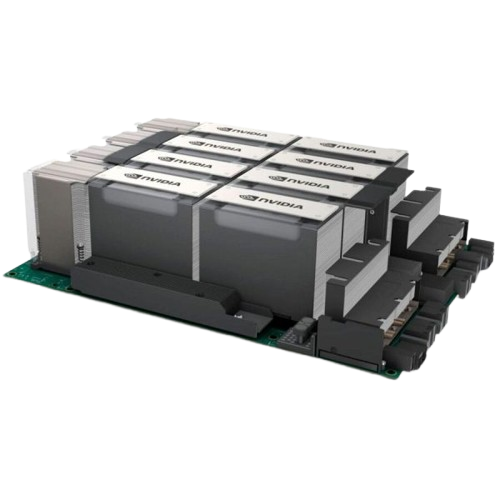
1128GB (8 x 141GB)
High Performance
Hopper HGX
Enterprise Ready
24/7 Support & Warranty
Scalable
For LLM & AI Workloads
Starting from
Estimated Ship Time: 3–4 weeks
(Depending on parts in stock and destination)
Managed Hosting & Referencing Services (Optional)
Technical Specifications
8U Rackmount
8 × NVIDIA HGX™ H200 141GB NVLink
2 × AMD EPYC™ 96Cores/192Threads 2.4GHz
2TB DDR5-6400
7.68TB NVMe SSD
1 × 960GB M.2 NVMe SSD
Dual 10GbE Ethernet
6 x Redundant 3000W Titanium Level
Ubuntu Linux 24.04 LTS
Qubrid AI Controller (3 Years License)
3 Years Next Business Day Onsite Support
8 × NVIDIA HGX™ H200 141GB NVLink GPU
Qubrid LLM Gen AI Appliance Server 8 x NVIDIA H200 141GB HGX NVLink GPU
What We Provide
We build end-to-end AI infrastructure solutions that help your enterprise deploy, scale, and stay ahead in the modern world.
Onsite Warranty Included
Comprehensive 3-year, next business day onsite hardware coverage to ensure maximum uptime. Certified technicians handle diagnosis and defective component replacement onsite.
Managed Hosting (Optional)
End-to-end managed inferencing and hosting. Qubrid handles data center and power provisioning, GPU telemetry, NVIDIA drivers, and CUDA updates without operational headaches.
AI Factory & Deployment (Optional)
Turnkey design and rapid deployment for large-scale GPU clusters. From high-speed InfiniBand/Ethernet networking and rack cabling to bare-metal provisioning and Kubernetes.
US Export Compliance
Expert guidance navigating complex U.S. export controls for advanced NVIDIA GPU systems. We coordinate end-use verification and documentation with OEM and NVIDIA partners.
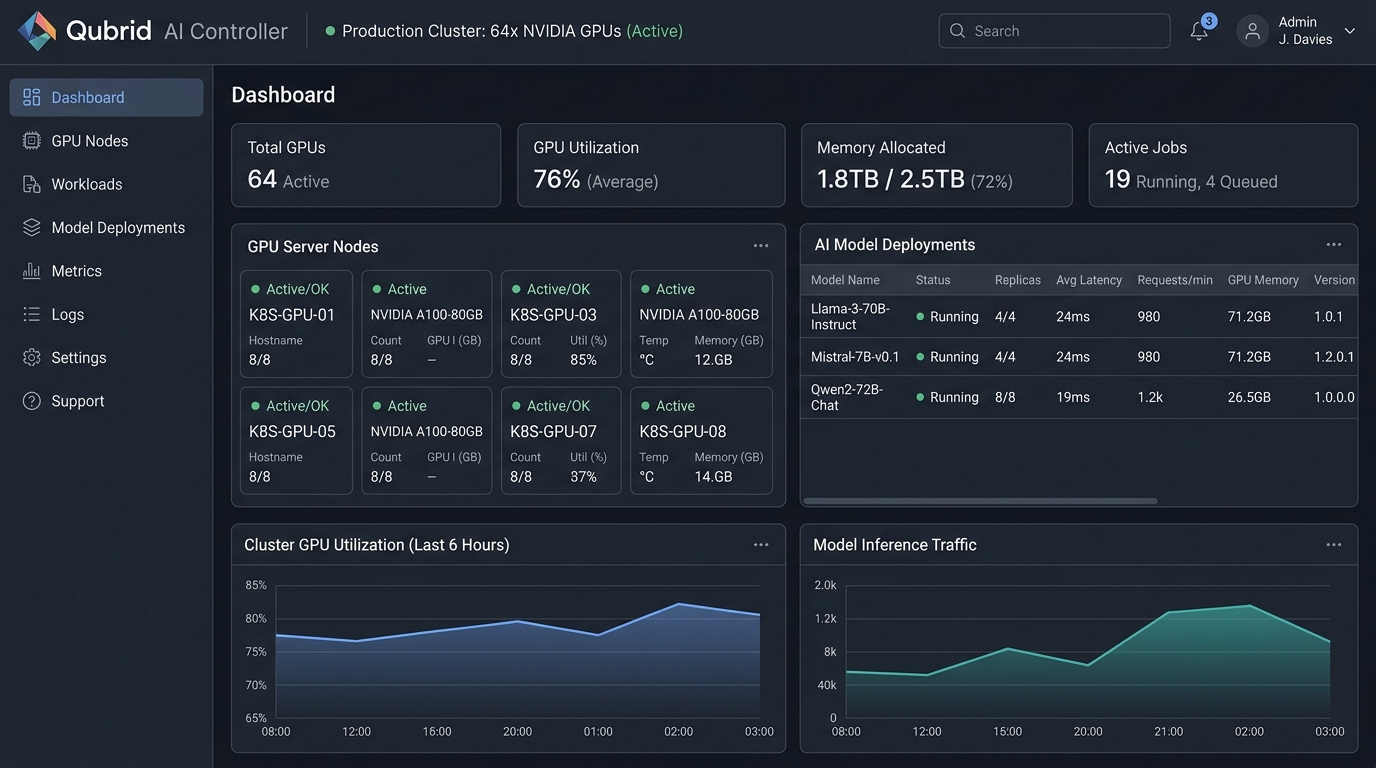
Pre-loaded OS & Qubrid
AI Controller
Every Qubrid AI system includes pre-installed Ubuntu Linux and Qubrid AI Controller software, optimized out-of-the-box for NVIDIA GPU workloads. Monitor cluster health, orchestrate workloads, and deploy AI models or RAG pipelines with minimal setup.
Centralized System & GPU Telemetry
Real-time monitoring for maximum uptime & performance.
Workload & Resource Orchestration
Efficiently manage and scale AI workloads across your cluster.
Optimized Ubuntu Linux Environment
Pre-configured, secure, and production-ready OS.
1-Click AI Model & RAG Deployment
Go from setup to inference in minutes, not days.